
A practical guide to organizing your information, connecting AI tools, and creating a searchable knowledge system
Instead of searching through dozens of notes, opening multiple PDF files, or revisiting old research, imagine asking an AI assistant a question and receiving a useful answer based on your own information—with references to the original sources.
That is the idea behind a personal AI knowledge base.
A personal AI knowledge base combines your notes, documents, research, and other information into an organized system that an AI assistant can search and use when answering questions. Depending on the tools you choose, you can build a simple knowledge assistant using a document-chat application or create a more advanced system with embeddings, vector search, and retrieval-augmented generation (RAG).
In this guide, you will learn how to build a personal AI knowledge base from scratch, import notes and PDFs, organize web research, choose suitable tools, connect an AI assistant, verify answers, and maintain the system over time.
The goal is not simply to store information. It is to make your knowledge easier to find, understand, reuse, and update.
Quick Summary
A personal AI knowledge base is a searchable collection of your notes, PDFs, web research, and other documents that an AI assistant can use to answer questions. To build one, collect your information, organize and clean it, store it in a suitable system, connect an AI retrieval tool, and test its answers against the original sources.
You can start with a simple document-chat application or build a more advanced private RAG system using a local language model, a document-processing pipeline, and a vector database.
Key Takeaways
- A personal AI knowledge base helps you retrieve information from your own documents using natural-language questions.
- You can include meeting notes, research papers, PDFs, bookmarks, articles, project documents, and personal writing.
- Organizing and cleaning your information is essential for reliable AI responses.
- Retrieval-augmented generation, or RAG, allows an AI model to use relevant information from your knowledge base.
- You can build a basic system without programming.
- Advanced users can create a private system using local AI models, OCR, embeddings, and vector databases.
- AI-generated answers should be checked against the original sources.
- Source metadata, document dates, permissions, and regular updates help maintain knowledge quality.
- A practical testing framework can reveal whether your knowledge base retrieves the right information.
- Start with a small, well-organized collection before importing your entire digital archive.
What Is a Personal AI Knowledge Base?
A personal AI knowledge base is a structured collection of information that an AI system can search, retrieve, and use to answer questions or assist with tasks.
It may contain:
- Personal notes
- PDF documents
- Research papers
- Web articles
- Meeting summaries
- Project documentation
- Product information
- Technical manuals
- Book highlights
- Saved webpages
- Spreadsheets
- Frequently asked questions
- Business procedures
- Learning materials
Unlike a conventional folder system, an AI knowledge base allows you to interact with your information using natural language.
For example, instead of manually searching through several documents, you could ask:
“What were the main conclusions from my research on local AI models, and which sources support them?”
The AI system searches the relevant content and generates an answer based on the information it can access.
However, an AI knowledge base is not automatically accurate. Its usefulness depends on the quality of the documents, the retrieval system, the AI model, and the way you verify its responses.
How Does a Personal AI Knowledge Base Work?
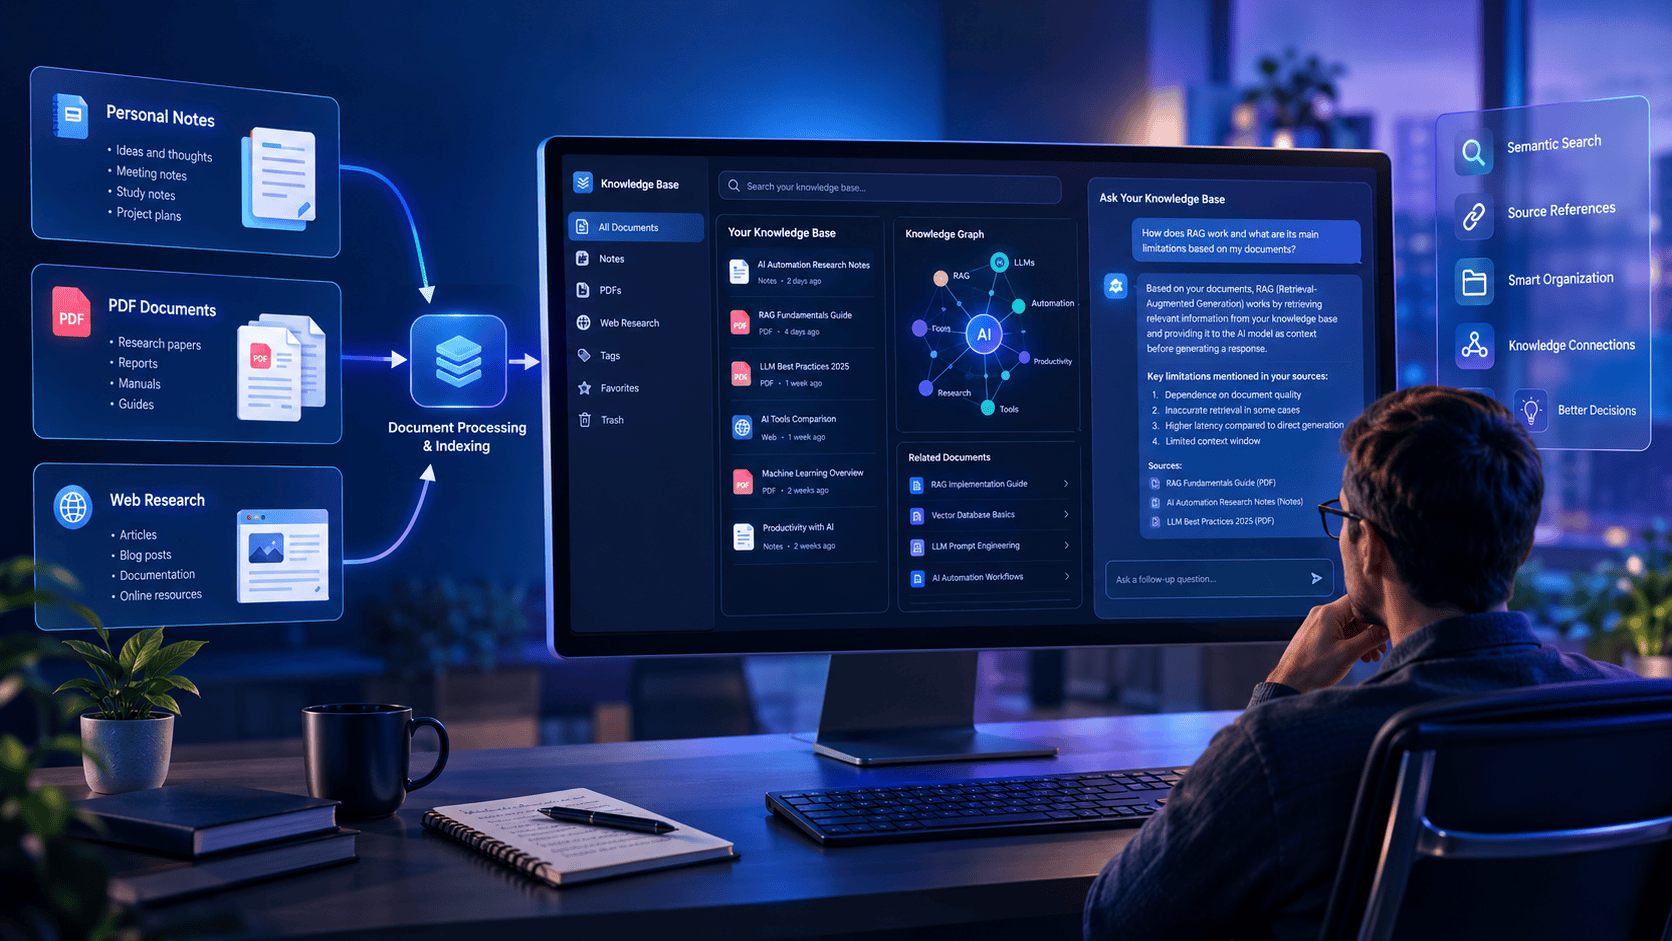
Most AI knowledge bases follow a workflow that combines document processing, search, and AI-generated responses.
The Basic Workflow
Notes, PDFs, and Web Research
↓
Document Collection
↓
Text Extraction and Cleaning
↓
Document Organization and Metadata
↓
Text Chunking
↓
Embeddings and Search Indexing
↓
User Question
↓
Relevant Information Retrieval
↓
AI-Generated Answer with Sources
This process is commonly implemented using retrieval-augmented generation, or RAG.
What Is RAG?
RAG is an approach in which an AI model retrieves relevant information from an external knowledge source before generating an answer.
Instead of relying only on information learned during model training, the system can use documents supplied by the user.
For example:
- You upload a PDF about AI automation.
- The system extracts and indexes the document.
- You ask, “What are the main automation opportunities described in this PDF?”
- The system searches the document for relevant sections.
- The AI model receives the retrieved content.
- The model generates an answer based on that content.
Important: RAG does not guarantee factual accuracy. If the document is incomplete, the search retrieves the wrong passages, or the AI misinterprets the evidence, the answer may still be incorrect.
Personal AI Knowledge Base: At a Glance
| Aspect | Description |
|---|---|
| Main purpose | Make personal information searchable and reusable through AI |
| Typical inputs | Notes, PDFs, webpages, research, documents, and saved information |
| Core technology | Document retrieval, semantic search, embeddings, and optionally RAG |
| Beginner approach | Use a document-chat or AI note-taking application |
| Advanced approach | Build a custom RAG system with a database and AI model |
| Search method | Keyword search, semantic search, or hybrid search |
| Output | AI answers, summaries, comparisons, extracted facts, and research assistance |
| Main challenge | Ensuring accurate retrieval and trustworthy answers |
| Privacy consideration | Understand where documents are stored and processed |
| Maintenance | Add new sources, update outdated documents, and remove duplicates |
Why Build a Personal AI Knowledge Base?
A knowledge base becomes especially useful when information is spread across multiple locations.
1. Find Information Faster
Instead of opening several files or searching through folders, you can ask a question in plain language.
For example:
“Find the notes where I discussed the advantages and limitations of local language models.”
The system can search for relevant concepts even when the exact wording differs.
2. Reuse Previous Research
Research often gets used once and then forgotten.
A knowledge base lets you revisit previous findings when:
- Writing a new article
- Preparing a report
- Comparing technologies
- Planning a project
- Creating educational content
- Developing a business process
3. Connect Information from Different Sources
Your notes may contain personal observations, while PDFs provide technical details and web research contains recent developments.
A suitable retrieval system can bring relevant information from these different sources into one conversation.
4. Improve Research Organization
A knowledge base can help you organize:
- Source URLs
- Research dates
- Author names
- Document topics
- Key findings
- Supporting evidence
- Open questions
- Follow-up tasks
This is particularly helpful for long-term research projects.
5. Reduce Repetitive Work
You can use an AI knowledge base to assist with:
- Summarizing documents
- Extracting important facts
- Comparing multiple sources
- Creating FAQs
- Drafting reports
- Finding related notes
- Preparing content outlines
- Reviewing previous decisions
6. Create a Personalized Learning Assistant
Students and professionals can use their own learning materials to build a searchable study assistant.
For example, a student could ask:
“Explain the difference between supervised and unsupervised learning using the concepts from my course notes.”
The assistant can retrieve relevant sections from the supplied materials.
7. Preserve Institutional or Personal Knowledge
A well-organized knowledge base can preserve useful information such as:
- Project decisions
- Technical explanations
- Lessons learned
- Research findings
- Process documentation
- Frequently encountered problems
It can become a long-term reference system rather than a temporary AI chat.
What Information Should You Add?
A personal AI knowledge base works best when you define its purpose before importing documents.
Recommended Knowledge Categories
| Category | Examples | Potential Uses |
|---|---|---|
| Personal notes | Ideas, observations, journals, meeting notes | Recall and reflection |
| Research | Articles, reports, papers, saved webpages | Research and comparisons |
| PDFs | Manuals, books, whitepapers, guides | Document analysis |
| Learning materials | Course notes, tutorials, study documents | Learning and revision |
| Work documents | SOPs, project files, technical references | Business assistance |
| Content research | Topic ideas, keyword research, source notes | Article creation |
| Product information | Specifications, manuals, troubleshooting documents | Product research |
| Project records | Decisions, requirements, milestones | Project management |
Start with One Knowledge Domain
Do not immediately upload every file you own.
A better approach is to begin with a focused collection, such as:
- AI research documents
- Personal learning notes
- A single business project
- Technical documentation
- Content research
- Academic papers
A focused knowledge base is easier to organize, test, and maintain.
Step-by-Step: How to Build a Personal AI Knowledge Base
Step 1: Define Your Main Objective
Before choosing an AI tool, determine what you want your knowledge base to accomplish.
Ask yourself:
- What information do I want to search?
- Who will use the system?
- Do I need private or cloud-based storage?
- Will I mainly ask questions or also automate tasks?
- Do I need citations and source links?
- How often will I update the documents?
- Do I need support for PDFs, images, or scanned documents?
- Am I comfortable using technical tools?
Example Objective
“I want to create a personal AI knowledge base containing my AI research notes, PDF documents, and saved web articles so I can quickly retrieve information while writing technical content.”
This objective helps determine the appropriate tools and workflow.
Step 2: Collect Your Notes, PDFs, and Web Research
Gather the information you want to include.
Notes
Possible sources include:
- Markdown files
- Plain-text files
- Word documents
- Note-taking applications
- Meeting summaries
- Research notebooks
- Personal knowledge-management systems
PDFs
Useful PDF sources include:
- Research papers
- Product manuals
- Technical guides
- Whitepapers
- Ebooks you have permission to use
- Business documentation
- Course materials
Web Research
You can collect:
- Webpage text
- Saved articles
- Research summaries
- Source URLs
- Author names
- Publication dates
- Important quotations
- Your own notes about the source
Recommended Folder Structure
Personal-AI-Knowledge-Base/
│
├── 01_Notes/
│   ├── AI-Research-Notes.md
│   ├── Meeting-Summaries/
│   └── Project-Ideas/
│
├── 02_PDFs/
│   ├── Research-Papers/
│   ├── Technical-Guides/
│   └── Manuals/
│
├── 03_Web-Research/
│   ├── AI-Articles/
│   ├── SEO-Research/
│   └── Source-Summaries/
│
├── 04_Processed-Documents/
│
├── 05_Metadata/
│
└── 06_Exports/
This structure is optional, but it makes your collection easier to maintain.
Step 3: Clean and Organize Your Information
Uploading documents without preparation can reduce the quality of search results.
Before importing your files:
Remove Unnecessary Duplicates
If the same PDF exists in multiple folders, keep a clearly identified copy where possible.
Separate Drafts from Final Documents
A knowledge base containing outdated drafts may retrieve information that no longer reflects your final decisions.
Check Document Quality
Look for:
- Missing pages
- Broken text extraction
- Unreadable scans
- Incorrect file names
- Incomplete downloads
- Duplicate content
- Outdated information
Use Descriptive File Names
Instead of:
Document1.pdf
ResearchFinalNew2.pdf
Notes123.md
Use:
2026-09-local-llm-comparison.pdf
AI-Automation-Research-Notes.md
PDF-Extraction-Workflow-Guide.pdf
Add Useful Metadata
Metadata helps the system distinguish documents that may contain similar information.
Recommended fields include:
| Metadata Field | Example |
|---|---|
| Title | Local AI Model Comparison |
| Topic | Local AI |
| Source Type | Research Paper |
| Author | Author’s name |
| Publication Date | 2026-09-10 |
| Added Date | 2026-09-25 |
| Source URL | Original webpage or document URL |
| Status | Draft, reviewed, or archived |
| Tags | LLM, benchmarks, privacy |
| Trust Level | Primary source, secondary source, or personal note |
Practical tip: Keep the original source URL and publication date whenever you import web research. This makes later verification much easier.
Step 4: Choose the Right AI Knowledge Base Approach
There are three common ways to build a personal AI knowledge base.
Approach 1: Document-Chat Applications
This is the easiest option for beginners.
You upload documents to an application and ask questions about them.
Suitable for:
- Small collections
- Quick PDF analysis
- Personal research
- Learning materials
- Users who do not want to code
Advantages:
- Simple setup
- Minimal technical knowledge
- Fast experimentation
- Often includes built-in document search
Limitations:
- Storage and usage limits may apply
- Privacy depends on the provider
- Customization may be limited
- Large collections may require a more structured system
Approach 2: AI Note-Taking and Knowledge-Management Applications
These tools combine note organization with AI-assisted search or question answering.
Suitable for:
- Daily notes
- Project documentation
- Personal knowledge management
- Connected notes and references
- Long-term information organization
Advantages:
- Combines notes and AI assistance
- Easier organization
- May support links between documents
- Useful for ongoing knowledge capture
Limitations:
- AI capabilities vary between products
- Some features may require a subscription
- Import and export support differs
- Advanced retrieval controls may be unavailable
Approach 3: Build a Custom RAG System
This approach gives you greater control over document processing, storage, retrieval, and AI models.
Suitable for:
- Developers
- Technical teams
- Privacy-sensitive projects
- Large or specialized document collections
- Custom AI workflows
Advantages:
- Greater customization
- Control over data processing
- Ability to use local models
- Flexible retrieval strategies
- Integration with automation tools
Limitations:
- Requires technical knowledge
- More setup and maintenance
- Document processing can be complex
- Retrieval quality needs testing
- Infrastructure may require additional resources
Comparison Table
| Feature | Document Chat | AI Knowledge App | Custom RAG |
|---|---|---|---|
| Setup difficulty | Low | Low to medium | Medium to high |
| Coding required | Usually no | Usually no | Often yes |
| Document search | Usually available | Usually available | Customizable |
| Long-term organization | Depends on the tool | Usually strong | Fully customizable |
| Privacy control | Provider-dependent | Provider-dependent | Can be self-hosted |
| Local AI support | Varies | Varies | Strong potential |
| Custom automation | Limited to moderate | Moderate | High |
| Maintenance | Low | Low to moderate | Moderate to high |
| Best starting point | Beginners | Knowledge workers | Developers and advanced users |
Step 5: Select the Tools for Your Knowledge Base
The tools you choose should match your technical skills, privacy requirements, document types, and budget.
There is no single application that is ideal for every knowledge-base project.
Tool Categories to Consider
| Tool Category | Purpose | What to Look For |
|---|---|---|
| Note-taking application | Store and organize notes | Markdown support, search, linking |
| Document-chat application | Ask questions about uploaded files | PDF support, source references, document limits |
| Knowledge-management application | Connect notes and research | Tags, backlinks, organization, AI search |
| Local AI interface | Run or interact with local models | Model support, document retrieval, privacy controls |
| Embedding model | Convert text into searchable numerical representations | Language support, retrieval quality, local execution |
| Vector database | Store and search embeddings | Filtering, scalability, metadata support |
| OCR tool | Extract text from scanned documents | Language support, layout handling |
| Automation platform | Move information between applications | API support, scheduling, integrations |
| Storage system | Keep original documents and processed data | Backup, permissions, version history |
Example AI Knowledge Base Stack
For a technical personal project, you could combine:
- Notes: Markdown files or a note-taking application
- PDF processing: A document extraction and OCR tool
- AI interface: Open WebUI or another suitable document-chat interface
- Language model: A cloud-based or locally hosted model
- Embeddings: An embedding model suitable for your language and documents
- Search: A vector database or a built-in retrieval system
- Automation: n8n or Make, if integrations are needed
- Storage: Local folders, a database, or a cloud storage provider
- Research references: Original URLs, publication dates, and source metadata
This is an example architecture, not a mandatory combination. Many beginner-friendly applications already include several of these components.
How to Choose
Choose a simpler application if you mainly want to:
- Upload PDFs
- Search notes
- Ask questions
- Summarize documents
- Avoid programming
Consider a custom or self-hosted system if you need:
- Local model execution
- Custom document-processing pipelines
- Advanced metadata filters
- Integration with business workflows
- Greater control over storage and access
Step 6: Import Your Notes into the Knowledge Base
Notes are often the most valuable part of a personal knowledge system because they contain your own observations, decisions, and interpretations.
However, notes are frequently inconsistent.
One note may contain complete explanations, while another may contain only a few keywords.
Recommended Note Format
A structured note can look like this:
# Topic: Retrieval-Augmented Generation

## Summary

RAG allows an AI model to retrieve relevant information
from an external knowledge source before generating an answer.

## Key Concepts

- Document ingestion
- Text chunking
- Embeddings
- Vector search
- Context retrieval
- Answer generation

## Practical Observations

A retrieval system should be tested with questions
whose answers are known from the original documents.

## Sources

- https://example.com/research-paper
- https://example.com/technical-guide

## Tags

RAG, AI, Knowledge Base, Semantic Search
This structure helps you preserve context and makes your notes easier to process.
Organizing Notes for Better Retrieval
Try to:
- Give each note a descriptive title.
- Use headings for major concepts.
- Separate facts from personal opinions.
- Include source links where applicable.
- Add dates to time-sensitive notes.
- Use consistent terminology.
- Avoid combining unrelated subjects in one document.
- Record whether a conclusion has been verified.
Example
Instead of writing:
“Local AI is useful because it is private and cheaper.”
A more useful note might say:
“Local AI can provide greater control over data processing because documents and model interactions may remain on locally managed infrastructure. However, privacy depends on the complete setup, including operating-system security, network configuration, model sources, and connected services. Hardware and electricity costs should also be considered when comparing local and cloud-based systems.”
The second version contains more context and makes it easier for an AI assistant to provide a qualified answer.
Step 7: Import and Process PDF Documents
PDFs are a major source of knowledge, but they can be difficult for AI systems to process correctly.
A PDF may contain:
- Selectable text
- Scanned pages
- Tables
- Images
- Footnotes
- Multiple columns
- Headers and footers
- Charts
- Mathematical formulas
- Embedded fonts
- An unusual reading order
Text-Based PDFs
If a PDF contains selectable text, a document-processing tool can often extract the text directly.
A typical process is:
PDF File
   ↓
Text Extraction
   ↓
Layout Cleanup
   ↓
Heading and Paragraph Detection
   ↓
Text Chunking
   ↓
Search Indexing
Scanned PDFs
Scanned documents may contain images of pages rather than actual text.
In that case, the system may need optical character recognition (OCR).
Scanned PDF
   ↓
Page Image Extraction
   ↓
OCR Processing
   ↓
Text Correction
   ↓
Document Structuring
   ↓
Search Indexing
OCR errors can affect search quality. Names, numbers, tables, and technical terms should be checked when accuracy matters.
PDF Processing Checklist
Before adding a PDF, check:
- Is the document readable?
- Is the text selectable?
- Are all pages present?
- Does the extracted text follow the correct reading order?
- Are tables preserved correctly?
- Are diagrams important to the meaning?
- Does the document contain confidential information?
- Is the source date recorded?
- Can the original document be accessed later?
Important Limitation
A text-only retrieval system may not fully understand information contained in images, charts, or diagrams.
If a PDF’s meaning depends on visual content, the knowledge-base pipeline may need image extraction, a vision-capable model, or a separate method for describing and indexing those visuals.
Step 8: Add Web Research Properly
Web research can make a personal knowledge base more useful, but webpages require additional care.
Unlike a static PDF, a webpage may change after you save it.
It may also contain:
- Advertisements
- Navigation menus
- Repeated text
- Comments
- Related-article sections
- Dynamic content
- Broken links
- Outdated information
Recommended Web Research Workflow
Find a Relevant Source
        ↓
Check Its Credibility
        ↓
Save the Source URL
        ↓
Capture the Relevant Content
        ↓
Record Author and Publication Date
        ↓
Add Your Own Summary
        ↓
Store the Source in the Knowledge Base
        ↓
Review and Update When Necessary
What Metadata Should You Save?
| Field | Example |
|---|---|
| Article title | Introduction to RAG |
| Author | Author or organization |
| Source URL | Original webpage |
| Publication date | Original publication date |
| Access date | Date you reviewed the source |
| Topic | AI Knowledge Management |
| Summary | Your concise explanation |
| Key findings | Important information |
| Limitations | Missing information or weaknesses |
| Tags | RAG, AI, Search |
| Review status | Unreviewed or verified |
Why Source Metadata Matters
Suppose you ask:
“What did my research conclude about AI search in 2025?”
If the knowledge base contains only extracted text without dates, the assistant may combine information from different periods.
Source dates and URLs make it easier to distinguish historical information from current information.
Do Not Treat Every Webpage as Verified Knowledge
A webpage may contain:
- Marketing claims
- Opinions
- Outdated statistics
- Unsupported conclusions
- User-generated content
- Information that conflicts with primary sources
A useful knowledge base should preserve the distinction between:
What a source says and what has been independently verified.
Step 9: Understand Text Chunking
When documents are imported into a RAG system, they are often divided into smaller sections called chunks.
A chunk may contain a paragraph, several paragraphs, or another meaningful section of text.
Why Chunking Is Necessary
A long document may contain hundreds of pages.
Sending the entire document to an AI model for every question can be inefficient or exceed the model’s context capacity.
Chunking allows the system to retrieve only the sections most relevant to the question.
Example
Original document:
Chapter 1: Introduction
Chapter 2: AI Knowledge Bases
Chapter 3: Document Processing
Chapter 4: Retrieval Systems
Chapter 5: Evaluation
After chunking:
Chunk 1: Introduction
Chunk 2: AI Knowledge Base Definition
Chunk 3: Knowledge Base Benefits
Chunk 4: Document Processing
Chunk 5: Text Extraction
Chunk 6: Retrieval Systems
Chunk 7: Evaluation Methods
If you ask:
“How should I test my AI knowledge base?”
The system should retrieve the section about evaluation rather than unrelated introductory content.
Common Chunking Strategies
| Strategy | Description | Suitable Use |
|---|---|---|
| Fixed-length chunking | Splits text into sections of a defined size | Simple documents |
| Paragraph-based chunking | Groups paragraphs together | Articles and notes |
| Heading-based chunking | Uses headings to preserve topic boundaries | Structured documents |
| Sentence-based chunking | Splits content according to sentences | Short, well-structured text |
| Semantic chunking | Groups text based on meaning | Complex research documents |
| Recursive chunking | Applies multiple splitting rules | Mixed document types |
What Is the Best Chunk Size?
There is no universal best chunk size.
The appropriate size depends on:
- Document structure
- Question complexity
- Embedding model
- Retrieval method
- AI model context capacity
- Amount of context needed for an answer
A useful starting point is to create chunks around meaningful sections rather than splitting text arbitrarily.
For technical documents, preserving a heading together with its explanation, examples, and relevant notes can be more useful than dividing the content at an arbitrary character count.
Chunking Mistakes to Avoid
- Splitting sentences in the middle
- Separating headings from their explanations
- Removing important document titles
- Mixing unrelated topics
- Creating chunks that are too small to provide context
- Creating chunks that contain too many unrelated subjects
- Discarding page numbers or source references
Step 10: Understand Embeddings and Semantic Search
Semantic search is one of the technologies that makes AI knowledge bases useful.
What Is an Embedding?
An embedding is a numerical representation of information, such as text.
An embedding model converts text into a vector—a list of numerical values that represents patterns in the text.
For example:
"How can I search my research notes?"
                  ↓
          Embedding Model
                  ↓
       [0.12, -0.44, 0.78, ...]
The actual vector contains many numerical dimensions.
Texts with related meanings may have similar representations, depending on the embedding model.
What Is Semantic Search?
Semantic search attempts to find information based on meaning rather than only matching exact words.
For example, a user might ask:
“How do I keep my documents private while using AI?”
A semantic search system may retrieve a note titled:
“Local Model Deployment and Data Protection”
even though the exact phrase “keep my documents private” does not appear in the note.
Keyword Search vs. Semantic Search
| Feature | Keyword Search | Semantic Search |
|---|---|---|
| Main method | Matches words or phrases | Compares meaning representations |
| Exact terms | Very useful | May be less precise for exact identifiers |
| Similar concepts | Can miss differently worded content | Often useful |
| Product part numbers | Usually highly effective | May require additional safeguards |
| Natural-language questions | Depends on wording | Often useful |
| Technical acronyms | Can work well | Depends on the embedding model |
| Numeric values | Exact matching is often important | Should be handled carefully |
| Best approach | Exact lookup | Conceptual retrieval |
Why Hybrid Search Can Help
A hybrid search system combines keyword and semantic search.
For example, if you search for a specific model number, keyword matching may be essential. If you ask a conceptual question, semantic search may retrieve more useful context.
Combining the two can improve retrieval for mixed collections.
Important: Search quality depends on implementation, document quality, indexing, and evaluation. Semantic search is not automatically superior for every query.
Step 11: Connect an AI Model to Your Knowledge Base
After your documents are processed and searchable, you need an AI model that can use the retrieved information.
The basic RAG process looks like this:
User Question
      ↓
Question Processing
      ↓
Knowledge Base Search
      ↓
Relevant Chunks Retrieved
      ↓
Context Sent to AI Model
      ↓
Answer Generated
      ↓
Sources Displayed or Returned
Example
You ask:
“What are the main advantages of using a local AI model for document analysis?”
The system may retrieve:
- Your notes about local AI
- A technical guide about local inference
- A document about document-processing privacy
- Your own comparison of cloud and local AI
The AI model then uses those retrieved passages to formulate an answer.
A Useful Instruction for the AI Assistant
You can configure the assistant with a rule such as:
“Answer questions using the retrieved documents whenever possible. Distinguish documented facts from personal notes and interpretations. If the available information is insufficient, say so. Do not invent citations, page numbers, quotations, or source claims. When possible, identify the document and relevant section supporting each important answer.”
This instruction can encourage more transparent responses, but it does not eliminate hallucinations or guarantee that every citation is correct.
Step 12: Add Source Citations and Verification
A personal AI knowledge base becomes much more useful when it shows where answers come from.
Without source references, it may be difficult to determine whether an answer is supported by your documents.
What a Useful Citation Can Include
- Document title
- Source URL
- Author
- Publication date
- Page number
- Section heading
- Document identifier
- Retrieved passage
Example Answer Format
Question: What are the benefits of a personal AI knowledge base?
Answer: A personal AI knowledge base can help organize information and make it easier to retrieve relevant notes and documents. Its usefulness depends on document quality, retrieval accuracy, and the AI model.
Sources:
Personal AI Knowledge Base Notes.md— Benefits sectionAI Knowledge Management Guide.pdf— Chapter 2- Original research article — Source URL
The exact citation format depends on the tool you use.
Verification Checklist
Before relying on an answer:
- Open the cited document.
- Find the relevant section.
- Check whether the answer accurately represents the source.
- Confirm that the source supports the specific claim.
- Check dates when the information is time-sensitive.
- Look for contradictory evidence.
- Separate personal notes from independently verified information.
The Difference Between Retrieval and Verification
These are two different tasks.
Retrieval asks:
“Can the system find relevant information?”
Verification asks:
“Does the information actually support the answer?”
A knowledge base may retrieve a relevant document but still produce an inaccurate conclusion.
Step 13: Create a Practical AI Knowledge Base Architecture
If you want more control over your personal knowledge system, you can build an architecture that separates document storage, processing, retrieval, and AI generation.
Recommended Architecture
                 INFORMATION SOURCES
       ┌──────────────┬──────────────┬──────────────┐
       │              │              │              │
     Notes          PDFs        Web Research    Other Files
       │              │              │              │
       └──────────────┴──────────────┴──────────────┘
                              │
                              ▼
                   DOCUMENT PROCESSING
                  ┌─────────────────────┐
                  │ Text Extraction     │
                  │ OCR                 │
                  │ Cleaning            │
                  │ Metadata            │
                  └─────────────────────┘
                              │
                              ▼
                       TEXT CHUNKING
                              │
                              ▼
                   EMBEDDING GENERATION
                              │
                              ▼
                     SEARCH INDEX
                  ┌─────────────────────┐
                  │ Vector Database     │
                  │ Keyword Index       │
                  │ Metadata Filters    │
                  └─────────────────────┘
                              │
                              ▼
                         USER QUERY
                              │
                              ▼
                    RETRIEVAL ENGINE
                              │
                              ▼
                      AI LANGUAGE MODEL
                              │
                              ▼
                   ANSWER + SOURCE LINKS
Main Components Explained
| Component | Responsibility |
|---|---|
| Source storage | Preserves original notes and documents |
| Document processor | Extracts and cleans text |
| OCR system | Converts scanned pages into searchable text |
| Metadata system | Stores dates, titles, URLs, and categories |
| Chunking system | Divides documents into retrievable sections |
| Embedding model | Creates numerical representations of text |
| Search index | Finds relevant content |
| Retrieval engine | Selects useful passages for a question |
| Language model | Generates the response |
| Citation system | Identifies supporting documents |
| Evaluation system | Measures retrieval and answer quality |
Example Technical Stack
For a self-hosted project, a possible stack could include:
| Layer | Example Options |
|---|---|
| Document storage | Local folders, object storage, or a document repository |
| Text extraction | PyMuPDF, Apache Tika, or another suitable parser |
| OCR | Tesseract or another OCR engine |
| AI interface | Open WebUI or a custom application |
| Local model runtime | Ollama or another compatible runtime |
| Embeddings | A suitable open-source embedding model |
| Vector database | Qdrant, Chroma, or another vector database |
| Workflow automation | n8n or Make |
| User interface | Web application or chat interface |
| Evaluation | Manually verified question-and-answer test sets |
These are examples of technologies you can evaluate. Their suitability depends on your operating system, document formats, hardware, and project requirements.
Step 14: Build a Beginner-Friendly Knowledge Base Without Coding
You do not need to build a custom RAG system to get started.
A beginner-friendly workflow can look like this:
Simple Setup
Notes + PDFs + Research
          ↓
Organized Folder
          ↓
Document-Chat Application
          ↓
Ask Questions
          ↓
Review Sources
          ↓
Save Useful Answers
Step-by-Step
1. Create a dedicated folder
Start with a small collection of documents related to one topic.
2. Remove duplicate and irrelevant files
Keep the collection focused.
3. Choose a document-chat application
Look for support for your file types, document limits, search features, and privacy requirements.
4. Upload a small batch
Begin with five to ten useful documents rather than hundreds of files.
5. Ask questions with known answers
For example:
“What is the main purpose of this document?”
“Which section discusses the limitations of the proposed method?”
“What does the source say about document privacy?”
6. Compare the answers with the documents
Check whether the system retrieves the correct information.
7. Improve the organization
Rename files, add metadata, and separate unrelated topics.
8. Expand gradually
Add more documents after the initial workflow performs satisfactorily.
Why Start Small?
A small collection makes it easier to identify:
- Missing documents
- Poor text extraction
- Incorrect retrieval
- Duplicate information
- Weak source references
- Confusing document names
It also reduces the time required to troubleshoot the system.
Step 15: Build a Personal AI Knowledge Base Using Local AI
If privacy and local processing are important to you, you can consider a locally hosted knowledge base.
A local setup may allow documents and AI processing to remain on infrastructure you control.
However, local hosting does not automatically guarantee privacy. Security also depends on operating-system protections, network settings, access controls, backups, connected services, and the software you use.
Example Local Workflow
Your Notes and PDFs
         ↓
Local Document Processor
         ↓
Local OCR, If Required
         ↓
Local Embedding Model
         ↓
Local Vector Database
         ↓
Local AI Model
         ↓
Private Knowledge Assistant
Potential Benefits
- Greater control over document storage
- Ability to work without an external AI API for some tasks
- Local processing options
- Customizable workflows
- Potentially useful for sensitive internal documentation
Potential Challenges
- Hardware requirements
- Model download sizes
- Slower processing on limited hardware
- Setup and maintenance
- OCR limitations
- Model quality differences
- Backup and security responsibilities
Hardware Considerations
The hardware you need depends on:
- Model size
- Quantization
- Available RAM
- GPU memory
- Number of documents
- Embedding model
- Number of simultaneous users
- Processing speed requirements
A small local model may work well for simple document questions, while more complex tasks may require a stronger model or additional resources.
Important Privacy Questions
Before selecting a tool, check:
- Where are uploaded documents stored?
- Are documents sent to external servers?
- Is data used for model training?
- Can you delete uploaded documents?
- Does the application retain conversation history?
- Are third-party integrations enabled?
- Can access permissions be configured?
- Are backups encrypted?
- Does the system expose documents through an API?
For sensitive information, review the provider’s current privacy documentation and security controls rather than relying only on product descriptions.
Step 16: Automate Your Knowledge Base
Once your knowledge base is working, you can automate parts of the process.
Automation is useful when new information arrives regularly.
Example Automation Workflow
New PDF or Research Article
              ↓
        File Detection
              ↓
       Text Extraction
              ↓
        Content Cleanup
              ↓
       Metadata Creation
              ↓
       Duplicate Checking
              ↓
       Search Index Update
              ↓
       Knowledge Base Ready
Possible Automation Tools
- n8n
- Make
- Python scripts
- Scheduled tasks
- Cloud storage triggers
- APIs
- Local file watchers
Example: Automated Research Capture
Suppose you regularly collect articles about AI automation.
An automated workflow could:
- Receive a saved article or document.
- Extract the relevant text.
- Record the title and source URL.
- Save the publication date.
- Generate a short summary.
- Assign topic tags.
- Store the document in the appropriate folder.
- Add it to the search index.
- Notify you when processing is complete.
Use Human Review for Important Information
Automation should not automatically treat every imported article as verified knowledge.
For important research, add a review stage:
New Source
    ↓
Automatic Processing
    ↓
Human Review
    ↓
Verified or Unverified Label
    ↓
Knowledge Base
This helps distinguish raw information from material that has been reviewed.
Step 17: Design a Useful Question-and-Answer Workflow
A knowledge base becomes more effective when you ask precise questions.
Weak Question
“Tell me about AI.”
This is too broad for a personal knowledge base.
Better Question
“Based on my uploaded research notes, explain how retrieval-augmented generation works and identify the documents that discuss its limitations.”
This question defines:
- The subject
- The source collection
- The expected explanation
- The need for supporting documents
Useful Prompt Templates
1. Summarize a Document
Summarize this document in five key points. Identify the main argument, supporting evidence, limitations, and any important dates.
2. Compare Sources
Compare the conclusions in these two documents. Identify agreements, disagreements, and claims that require further verification.
3. Find Supporting Evidence
Find the sections in my knowledge base that support this statement. If the available documents do not support it, explain what is missing.
4. Create a Research Brief
Using only the relevant documents in my knowledge base, create a structured research brief with an introduction, key findings, evidence, limitations, and source references.
5. Identify Contradictions
Search my knowledge base for conflicting statements about this topic. Identify the documents, dates, and reasons the conclusions may differ.
6. Find Related Notes
Find notes related to this topic and group them by theme. Include the title and source location for each note.
7. Create a Study Guide
Use my uploaded learning materials to create a study guide with definitions, examples, practice questions, and references to the relevant sections.
Step 18: Evaluate Your AI Knowledge Base
A knowledge base should be tested before you depend on it for important research or business decisions.
A system may appear useful during casual conversations but fail when asked specific questions.
Practical Testing Framework
Create a small test set of questions whose answers you already know.
Test Categories
| Test Type | Example Question | What to Measure |
|---|---|---|
| Direct lookup | What is the title of the document? | Basic retrieval |
| Fact retrieval | What conclusion does the report state? | Correctness |
| Semantic search | Find notes about document privacy | Meaning-based retrieval |
| Multi-document comparison | Compare two research papers | Cross-document retrieval |
| Metadata filtering | Find documents published in 2026 | Metadata accuracy |
| Source citation | Which page supports this claim? | Citation correctness |
| Negative question | Do my documents contain evidence for this claim? | Ability to acknowledge missing information |
| Contradiction search | Which sources disagree? | Conflict identification |
| OCR test | What does the scanned page say? | Extraction quality |
| Outdated information | What was the conclusion at a specific date? | Temporal accuracy |
Example Evaluation Table
| Question | Expected Source | Retrieved Source | Answer Correct? | Citation Correct? | Notes |
|---|---|---|---|---|---|
| What is RAG? | RAG Guide | RAG Guide | Yes/No | Yes/No | — |
| What are the limitations? | Research Paper A | Retrieved document | Yes/No | Yes/No | — |
| What did the 2025 report say? | 2025 Report | Retrieved document | Yes/No | Yes/No | Check date |
| Which source supports this claim? | Source B | Retrieved document | Yes/No | Yes/No | Verify passage |
Important Evaluation Metrics
Retrieval Accuracy
Did the system retrieve the correct document or passage?
Answer Accuracy
Did the AI answer the question correctly?
Citation Accuracy
Does the cited source actually support the answer?
Completeness
Did the system retrieve all important information required for the question?
Hallucination Rate
How often does the AI introduce unsupported information?
Response Time
How long does the system take to retrieve information and generate an answer?
Practical Testing Recommendation
Start with 20–30 questions covering different document types and difficulty levels.
Record the results in a spreadsheet or table. When you change the embedding model, chunking method, retrieval settings, or language model, repeat the tests and compare the results.
Do not assume that a newer model or a larger knowledge base will automatically produce better answers.
Step 19: Keep Your Knowledge Base Updated
A knowledge base can become less useful when its contents are outdated or poorly organized.
This is especially important for:
- Technology research
- Software documentation
- Product specifications
- Pricing information
- Legal or regulatory material
- Business procedures
- Industry statistics
Recommended Maintenance Schedule
| Task | Suggested Frequency |
|---|---|
| Add new notes | As needed |
| Review newly imported documents | Weekly |
| Remove obvious duplicates | Monthly |
| Check outdated research | Monthly or quarterly |
| Review important source links | Periodically |
| Test retrieval quality | After major changes |
| Review permissions | Regularly |
| Back up original documents | Based on document importance |
| Re-index modified documents | Whenever required |
These are practical starting points, not universal schedules.
Add Document Status Labels
You can use labels such as:
- New
- Unreviewed
- Reviewed
- Verified
- Outdated
- Archived
- Needs Update
Track Document Versions
For documents that change frequently, record:
- Original publication date
- Last updated date
- Date imported
- Version number
- Source URL
- Review status
This prevents the system from treating different versions as identical information.
Step 20: Protect Your Personal Knowledge Base
Your knowledge base may contain private information, business documents, research notes, or confidential material.
Security should be considered from the beginning.
Privacy and Security Checklist
1. Review Your AI Provider’s Policies
Understand how uploaded documents and conversations are handled.
2. Avoid Unnecessary Sensitive Data
Do not upload confidential information unless you understand the risks and have permission to process it.
3. Use Access Controls
Restrict access to the knowledge base and its underlying files.
4. Secure Your Local System
Use operating-system security, strong authentication, updates, and appropriate network protections.
5. Protect Backups
Backups may contain the same sensitive information as the original knowledge base.
6. Check Connected Integrations
An automation workflow may send documents to external services.
7. Keep Original Sources
Do not rely only on extracted text. Preserve the original documents where possible.
8. Review Sharing Settings
Make sure private notes and documents are not accidentally exposed through public links or shared workspaces.
9. Remove Unnecessary Documents
Delete information that you no longer need, subject to applicable retention requirements.
10. Check Permissions Before Sharing
If your knowledge base is used by a team, decide which documents each person can access.
Recommended AI Knowledge Base Stack
The following stack is a practical example for someone who wants to organize research, notes, PDFs, and web content.
| Requirement | Example Tool or Approach | Why It May Help |
|---|---|---|
| Notes | Markdown or a note-taking application | Easy organization and portability |
| PDF analysis | Document-chat application | Quick document question answering |
| Local AI interface | Open WebUI | Can support local AI workflows |
| Local model runtime | Ollama | Useful for running compatible models locally |
| Document extraction | PDF parser | Converts PDF text into processable content |
| OCR | OCR engine | Makes scanned documents searchable |
| Search | Vector database | Supports semantic retrieval |
| Metadata | Structured fields or database | Helps filter and organize documents |
| Automation | n8n or Make | Connects sources and processing steps |
| Storage | Local folders or cloud storage | Preserves original documents |
| Evaluation | Spreadsheet or test database | Tracks retrieval and answer quality |
Tool selection note: Features, integrations, pricing, supported models, and privacy policies can change. Verify the current capabilities of each tool before selecting it for a production workflow.
Common Mistakes to Avoid
Mistake 1: Uploading Everything Without Organization
A large collection of unrelated documents can make retrieval and maintenance more difficult.
Solution: Start with one topic and organize the documents before importing them.
Mistake 2: Ignoring Document Quality
Poor OCR, missing pages, and broken text extraction can produce incomplete answers.
Solution: Inspect extracted content, especially for scanned PDFs and complex layouts.
Mistake 3: Treating AI Answers as Automatically Correct
An AI-generated answer may sound convincing even when the supporting evidence is weak.
Solution: Verify important claims against the original sources.
Mistake 4: Forgetting Source Metadata
Without dates and URLs, it may be difficult to understand where information came from.
Solution: Store source metadata with every research document.
Mistake 5: Using Only Semantic Search
Semantic search may not be ideal for exact product codes, names, identifiers, or numerical values.
Solution: Consider keyword or hybrid search for precise queries.
Mistake 6: Using Poor Chunking
Chunks that are too small may lose context, while excessively large chunks may contain unrelated information.
Solution: Preserve meaningful sections and evaluate different chunking strategies.
Mistake 7: Mixing Facts and Personal Opinions
An AI assistant may not know whether a statement is an established fact or your personal interpretation.
Solution: Label notes as facts, observations, opinions, hypotheses, or verified findings.
Mistake 8: Ignoring Outdated Information
Old documents may be retrieved for questions about current topics.
Solution: Record dates and use time-based filters where appropriate.
Mistake 9: Importing Confidential Information Without Reviewing Privacy
Some systems process uploaded documents on external infrastructure.
Solution: Review data-handling policies and use appropriate security controls.
Mistake 10: Building a Complex System Too Early
A custom RAG system may require considerable effort before it becomes useful.
Solution: Begin with a simple workflow and introduce technical components only when they solve a real problem.
Personal AI Knowledge Base: Example Use Cases
1. Content Research
A content creator can store:
- Research notes
- Source articles
- PDF reports
- Keyword research
- Expert interviews
- Technical documentation
The AI assistant can help locate relevant information when planning a new article.
Example Question
“Find the research notes and source documents related to AI automation workflows, then group them into possible article sections.”
2. Student Learning Assistant
A student can import:
- Lecture notes
- Textbooks
- Study guides
- Research papers
- Practice questions
The AI assistant can explain concepts using the supplied material.
Example Question
“Explain this topic using my course notes and identify the sections I should revise.”
3. Business Documentation Assistant
A business can organize:
- Standard operating procedures
- Product manuals
- Internal guides
- Troubleshooting documents
- Training materials
The assistant can help employees locate relevant procedures.
Example Question
“Which document explains the procedure for handling this customer issue?”
For business use, access controls and source verification are especially important.
4. Technical Research
Developers and researchers can store:
- Technical papers
- API documentation
- Project notes
- Architecture decisions
- Experiment results
- Benchmark reports
The AI assistant can help compare approaches and locate previous findings.
Example Question
“Compare the approaches described in my research notes and identify the trade-offs mentioned by each source.”
5. Personal Productivity
A personal knowledge base can include:
- Meeting summaries
- Project plans
- Ideas
- Personal learning notes
- Checklists
- Long-term goals
The AI assistant can help retrieve information from previous work.
Example Question
“Find the notes where I recorded unresolved tasks for this project.”
How to Improve Your AI Knowledge Base Over Time
A useful knowledge base is not a one-time project. It improves as you learn which documents, retrieval methods, and workflows produce reliable results.
Improvement Strategy
Phase 1: Start Small
Import a focused collection of notes and PDFs.
Phase 2: Improve Organization
Add consistent titles, categories, dates, and source metadata.
Phase 3: Test Retrieval
Create questions with known answers and measure whether the system finds the correct information.
Phase 4: Improve Document Processing
Fix OCR problems, remove duplicates, and improve chunking.
Phase 5: Add Search Improvements
Consider metadata filters, keyword search, semantic search, or hybrid retrieval.
Phase 6: Add Automation
Automate repetitive tasks such as document ingestion and indexing.
Phase 7: Improve Privacy
Review storage, access permissions, backups, and external integrations.
Phase 8: Expand Carefully
Add additional topics only after the existing system is organized and useful.
Frequently Asked Questions
1. What is a personal AI knowledge base?
A personal AI knowledge base is a collection of your notes, PDFs, research, and other information that an AI system can search and use to answer questions.
2. Can I build an AI knowledge base without coding?
Yes. Many document-chat and knowledge-management applications allow you to upload documents and ask questions without writing code.
3. Can I use PDFs in a personal AI knowledge base?
Yes. PDFs can be processed and indexed for AI search. Text-based PDFs are generally easier to process than scanned documents, which may require OCR.
4. Can I add web research to my knowledge base?
Yes. You can save relevant webpage content, source URLs, publication dates, and your own research notes. Check the source’s reliability and any applicable content-use restrictions.
5. What is the difference between a knowledge base and RAG?
A knowledge base is the collection of information. RAG is a method that retrieves relevant information from a knowledge source and provides it to an AI model when generating an answer.
6. Is a personal AI knowledge base private?
It depends on how it is built. A cloud-based system may process documents on a provider’s infrastructure. A self-hosted system can provide more control, but privacy still depends on security and configuration.
7. Can an AI knowledge base replace traditional note-taking?
Not necessarily. Note-taking remains useful for capturing and organizing information. An AI knowledge base adds search and question-answering capabilities to that information.
8. How many documents should I upload?
There is no universal limit that guarantees good performance. Start with a small, focused collection and expand after testing retrieval quality.
9. Can a personal AI knowledge base work with scanned PDFs?
Yes, if the system supports OCR or another method of extracting text from scanned pages. OCR accuracy should be checked for important documents.
10. Can I use a local AI model for my knowledge base?
Yes. A local AI model can be combined with local document processing, embeddings, and a search system. The required hardware depends on the models and workload.
11. Why does my AI knowledge base sometimes give incorrect answers?
Possible causes include poor document extraction, missing information, incorrect retrieval, outdated sources, weak prompts, or AI hallucinations.
12. How can I improve answer accuracy?
Improve document quality, preserve source metadata, test retrieval, use appropriate chunking, verify citations, and instruct the AI to acknowledge when evidence is insufficient.
13. Can I use my knowledge base for content creation?
Yes. It can help retrieve research, compare sources, organize article ideas, and prepare content outlines. Important claims should still be checked against the original sources.
14. Should I use keyword search or semantic search?
Both have advantages. Keyword search is useful for exact terms and identifiers, while semantic search can help find conceptually related information. A hybrid approach may be useful for mixed document collections.
15. Does a personal AI knowledge base need a vector database?
No. A simple document-chat application may handle retrieval internally. A vector database becomes useful when you need more control over embeddings, search, metadata, or system architecture.
Final Checklist: Is Your AI Knowledge Base Ready?
Use this checklist before relying on your knowledge base for regular work.
- I have defined the purpose of my knowledge base.
- I have selected a focused topic or collection.
- My documents have descriptive names.
- I have removed unnecessary duplicates.
- I have checked PDF extraction quality.
- I have processed scanned documents where necessary.
- I have recorded source URLs and dates.
- I have separated facts from personal opinions.
- I have selected a suitable AI retrieval tool.
- I have tested the system with known questions.
- I have checked whether citations support the answers.
- I understand how my documents are stored and processed.
- I have a backup strategy.
- I have a process for updating outdated information.
- I know how to remove or correct documents.
Conclusion
Building a personal AI knowledge base is a practical way to turn scattered notes, PDFs, and web research into a searchable information system.
You do not need to begin with a complex technical architecture. A simple document-chat application may be enough to get started. As your collection grows, you can introduce better metadata, structured document processing, semantic search, RAG, automation, and local AI models.
The most important factor is not the number of documents you upload. It is the quality, organization, and reliability of the information your system retrieves.
A well-designed knowledge base can help you find previous research, understand technical documents, prepare content, organize learning materials, and reuse information more effectively.
Start with a small collection, test it with real questions, verify the answers, and improve the system gradually.
Your personal knowledge becomes more valuable when you can find and use it when you need it.
Expert Tips for Building a Better AI Knowledge Base
Tip 1: Preserve the Original Source
Always keep the original PDF, note, or webpage reference alongside extracted content.
Tip 2: Use Meaningful Document Titles
Good titles improve both human organization and automated document management.
Tip 3: Separate Raw Research from Verified Findings
A saved article is not necessarily a confirmed fact.
Tip 4: Record Dates
Dates are essential when working with changing technologies, product information, or historical research.
Tip 5: Test Before Expanding
A small, reliable knowledge base is easier to improve than a large, poorly organized archive.
Tip 6: Keep Your AI Instructions Clear
Tell the assistant to use available sources, distinguish uncertainty, and avoid inventing citations.
Tip 7: Use Multiple Search Methods When Appropriate
Exact search and semantic search serve different purposes.
Tip 8: Review Privacy Before Uploading Documents
Understand where your information is processed and who can access it.
Tip 9: Keep the System Simple
Add complexity only when it solves a specific problem.
Tip 10: Reevaluate Your Workflow Regularly
Your document types, research habits, and AI requirements may change over time.
What Is a Personal AI Knowledge Base?
A personal AI knowledge base is an organized collection of notes, PDFs, web research, and other information that an AI system can search and use to answer questions. It typically combines document storage, text processing, search, and AI-generated responses to help users retrieve and reuse their own knowledge.
How Do You Build a Personal AI Knowledge Base?
To build a personal AI knowledge base, collect your notes, PDFs, and web research; organize and clean the documents; add source metadata; choose a document-chat application or custom RAG system; process the documents for search; connect an AI model; and test answers against the original sources. Start with a small collection and expand it as your retrieval workflow improves.
Also Read
- Make vs n8n for AI Automation
- How to Build an AI Assistant Without Code
- How to Set Up Open WebUI for a Private Local AI Chat Experience
- Local AI vs Cloud AI: Cost, Speed, and Privacy Comparison
- How to Create a Private Document QA Bot Using AnythingLLM
- Best Free AI Note-Taking Apps for Meetings and Lectures
- How to Use AI for E-commerce Product Description Generation at Scale
- How to Use AI in Excel and Google Sheets to Automate Formulas
- How to Build an Interactive AI Resume That Stands Out to Recruiter AI
- How Freelancers Can Package AI Automation Services as High-Ticket Offers
- Best AI Browser Extensions for Writing, Research & Productivity
- Best AI Voice Generator Tools for Video Editing (Free vs Paid)
- How to Turn Audio Recordings into Published Articles with AI
- AI Ethics for Creators: How to Disclose AI-Generated Content

Leave a Reply